How we helped Momentum eliminate manual data entry with an intelligent forms pipeline
This financial services automation case study details our work with Momentum, a major player in the financial services sector in 2026. After a comprehensive AI readiness review highlighted systematic bottlenecks, we designed a custom pipeline to automate manual form processing. Here is how we helped them transition from manual labor to automated exception handling.
What we walked into
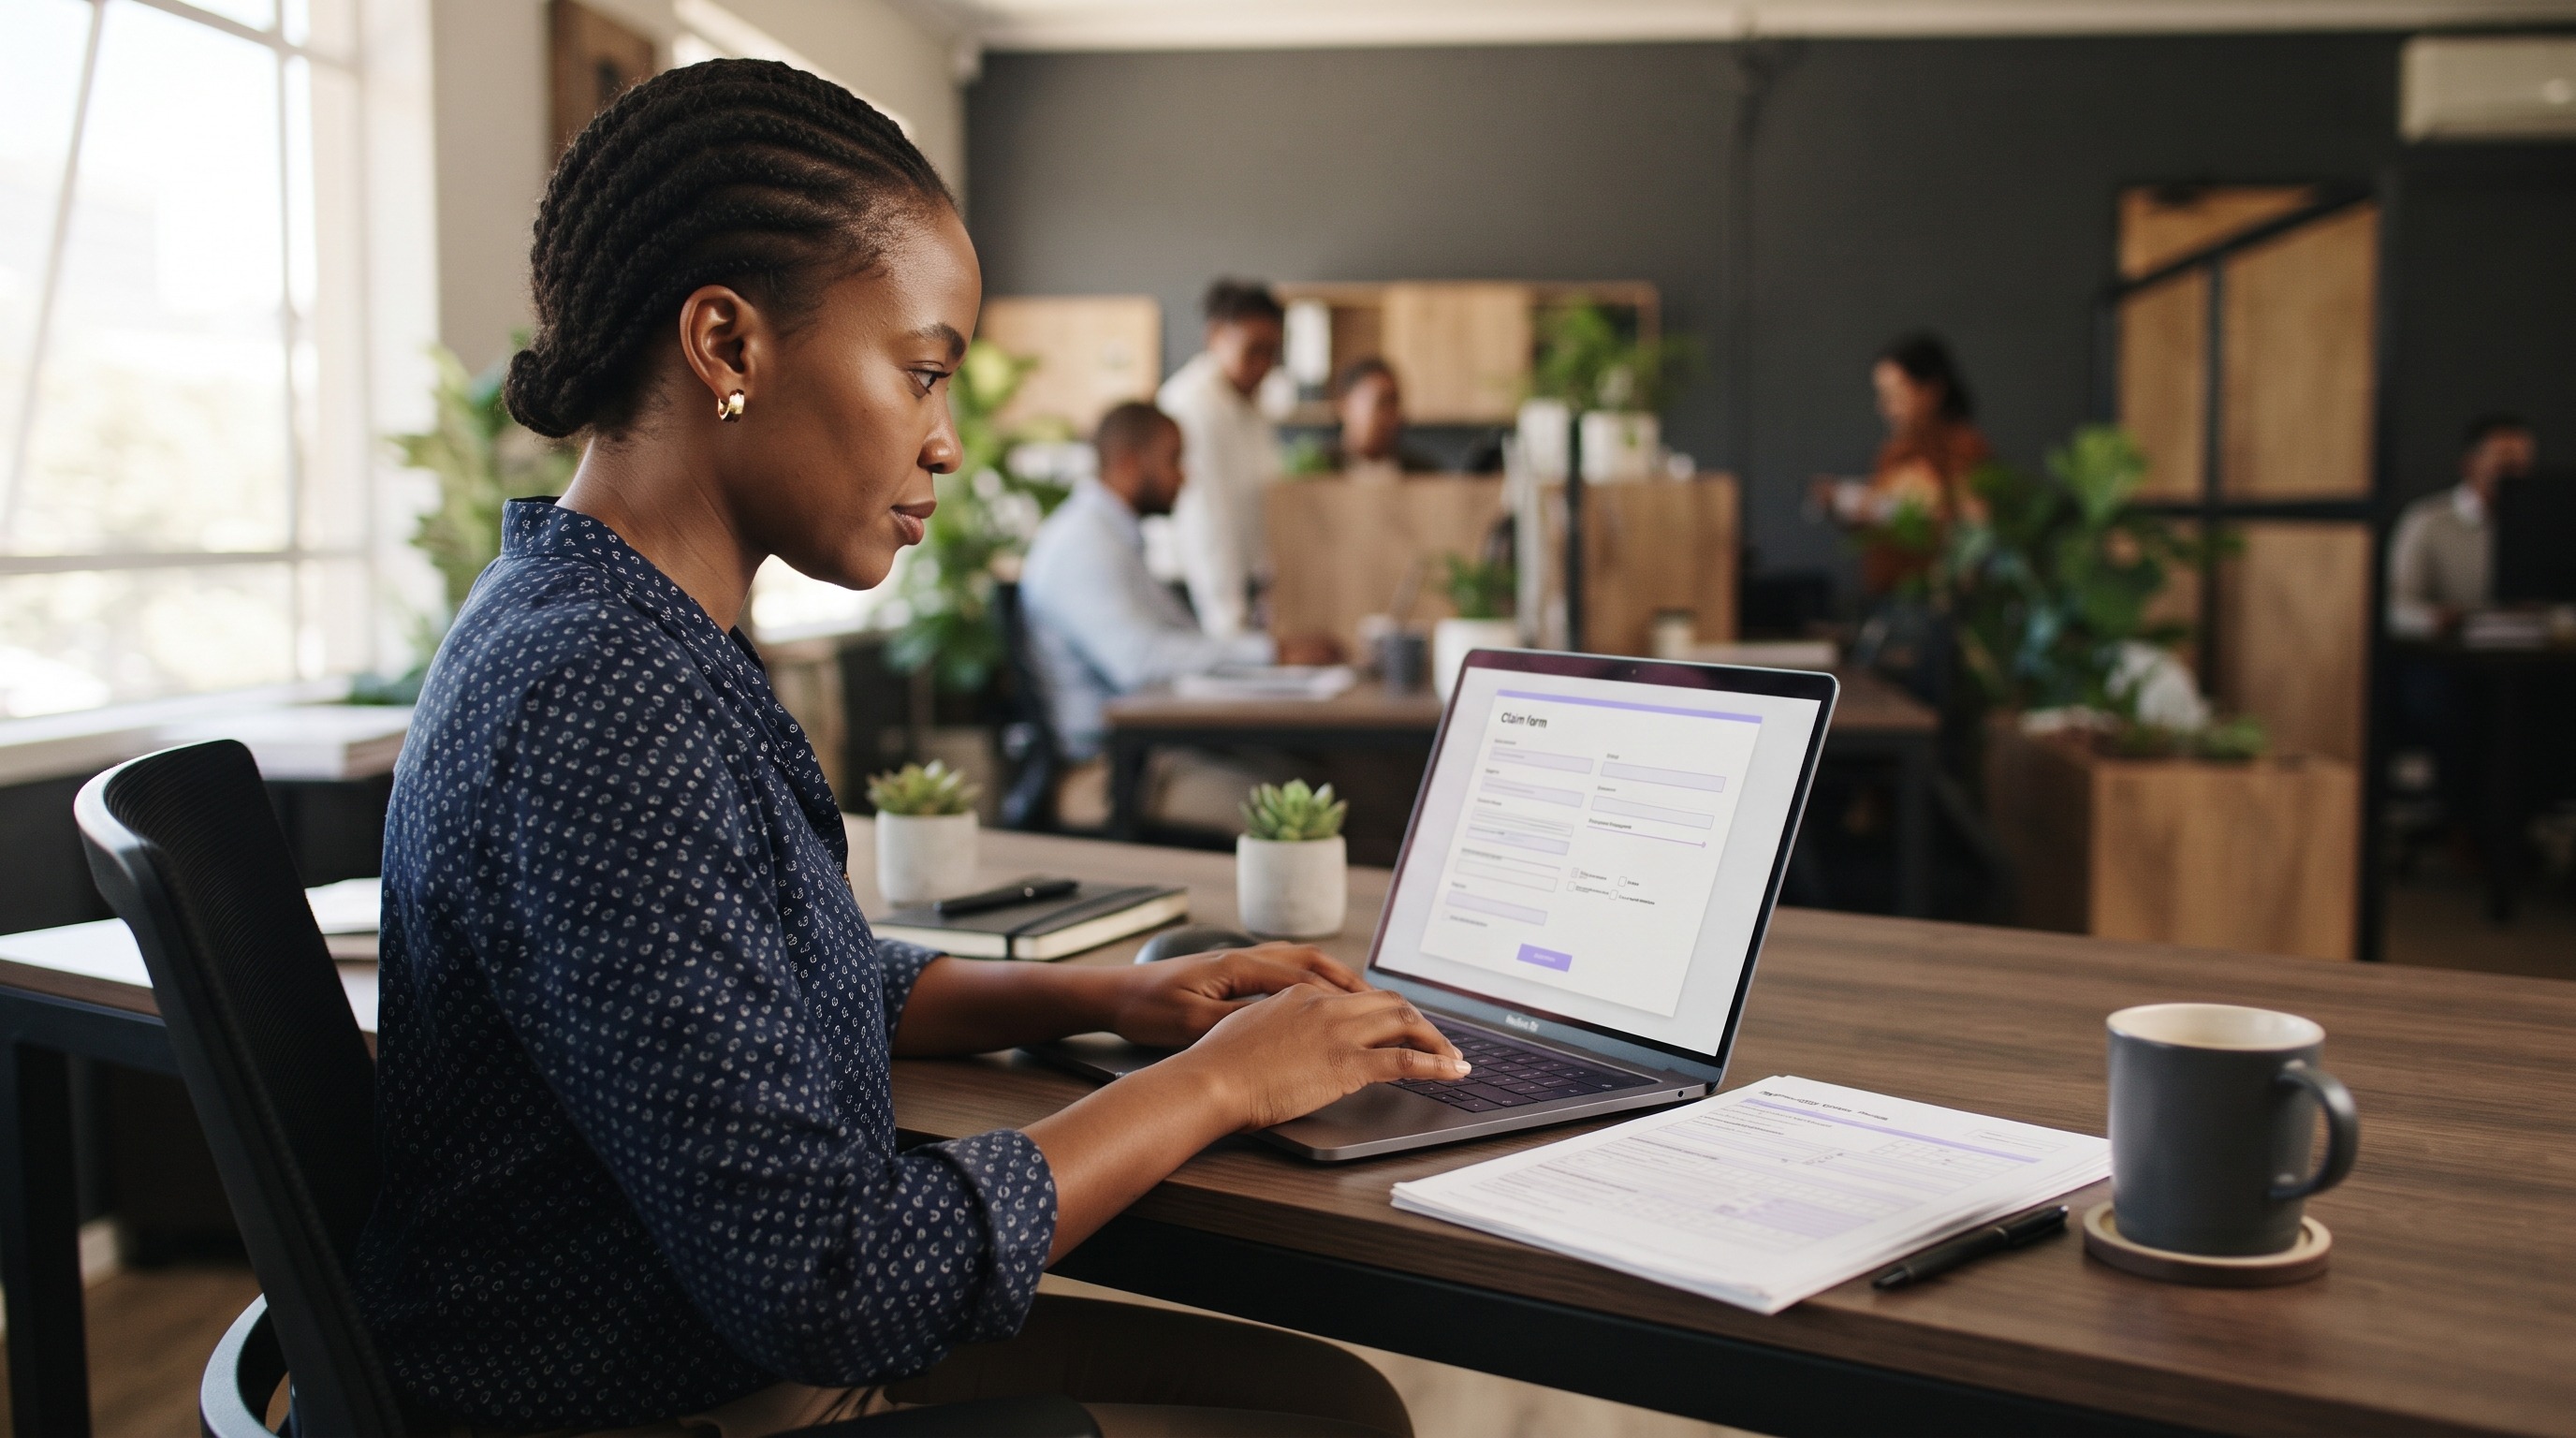
Despite Momentum’s advanced digital infrastructure, several lines of business were severely bogged down by manual back-office tasks. Staff in multiple departments were physically reading scanned forms and manually typing data into legacy databases. This repetitive data-entry process delayed client onboarding, introduced human errors, and created an operational bottleneck across the group.
An internal AI readiness audit across their business units confirmed that manual keying was the primary drag on throughput. Highly trained operations specialists were spending up to half their workdays acting as manual bridges between document scans and core software. It became clear that we needed to plug this operational leak to allow their talented workforce to focus on high-value tasks.
The system
We engineered an end-to-end document processing pipeline specifically tailored to the strict security and compliance standards of the financial services sector. The system consists of four main phases: capture, extraction, validation, and automated write-back. This modular approach ensures that each step of the document lifecycle is optimized for speed and data integrity.
The capture phase automatically aggregates inbound documents from secure email accounts, customer portals, and shared drives. Once captured, the extraction engine utilizes advanced language models to identify and extract key fields from structured and unstructured PDFs. Unlike legacy OCR tools, this engine understands context, meaning it can accurately pull variable data like policy numbers, dates, and financial figures.
After extraction, a validation engine automatically runs the data through a series of rigorous business rules and cross-checks it against existing client records. If a record contains an anomaly or falls below a set confidence score, the system routes it to a human reviewer for quick exception handling. Otherwise, clean data is automatically written back to Momentum’s core databases via secure APIs, bypassing manual handling entirely.
What changed
The immediate impact of the new system was that manual data entry dropped off the critical path entirely. Operators no longer spend their mornings transcribing numbers from scanned application forms into legacy desktops. Instead, they act as high-level validators, logging into a centralized queue to review and approve flagged exceptions.
This shift has dramatically accelerated the company's overall processing times, shortening cycle times from several days to just a few minutes. Additionally, data quality has surged because transcription errors have been designed out of the system. Momentum is now scaling this exact architectural pattern to streamline other document-heavy operations across the entire group.
Who this is for
This case study is designed for operations directors, chief operating officers, and technology leaders within the financial services sector. If your teams are spending more than 20 percent of their day copying and pasting data between files, this system is for you. It is built for organizations that need to scale transactional capacity without experiencing a linear growth in headcount.
If you are reading this financial services automation case study to find a practical blueprint, this architecture offers a direct path forward. It successfully bridges the gap between old legacy core systems and modern document intelligence. By implementing a similar structure, you can unlock immediate capacity in your back office while reducing operational risk.
Common questions
How long does a pipeline like this take to implement?
An enterprise-grade document processing pipeline is typically scoped, built, and integrated into your staging environment within 8 to 12 weeks. Because the architecture is highly modular, we can launch the extraction engine early and layer in validation rules over time.
How does the system handle low-quality scans or handwriting?
The extraction engine leverages advanced vision-language models that can interpret complex handwriting and low-resolution digital scans. If a document's readability is compromised, the system automatically routes it to the human exception queue for manual approval.
Is customer and financial data kept secure during processing?
Data security is built into every layer of the architecture to ensure complete compliance with local and international privacy regulations. All data is processed in memory using secure API endpoints, meaning no customer information is stored permanently on external servers.
Summary
Modernizing your back office does not require a complete overhaul of your legacy core software. By targeting the manual keying bottleneck at Momentum, we created an intelligent, automated pipeline that handles the heavy lifting of data extraction. The operations team has successfully transitioned from data entry clerks to exception managers, positioning the group for rapid, scalable growth.
Next step
If you want to implement a similar intelligent extraction pipeline in your business, explore these resources:
- Hire Augmented AI
- Case study
- Business process automation consultant
- AI automation consultant South Africa
Hire the studio on work with us. Short case study: Financial services forms automation case study. Business process automation consultant · AI automation consultant South Africa